Why Local AI?
Running AI models on your own infrastructure eliminates cloud‑dependent latency, protects sensitive data and removes recurring subscription fees.
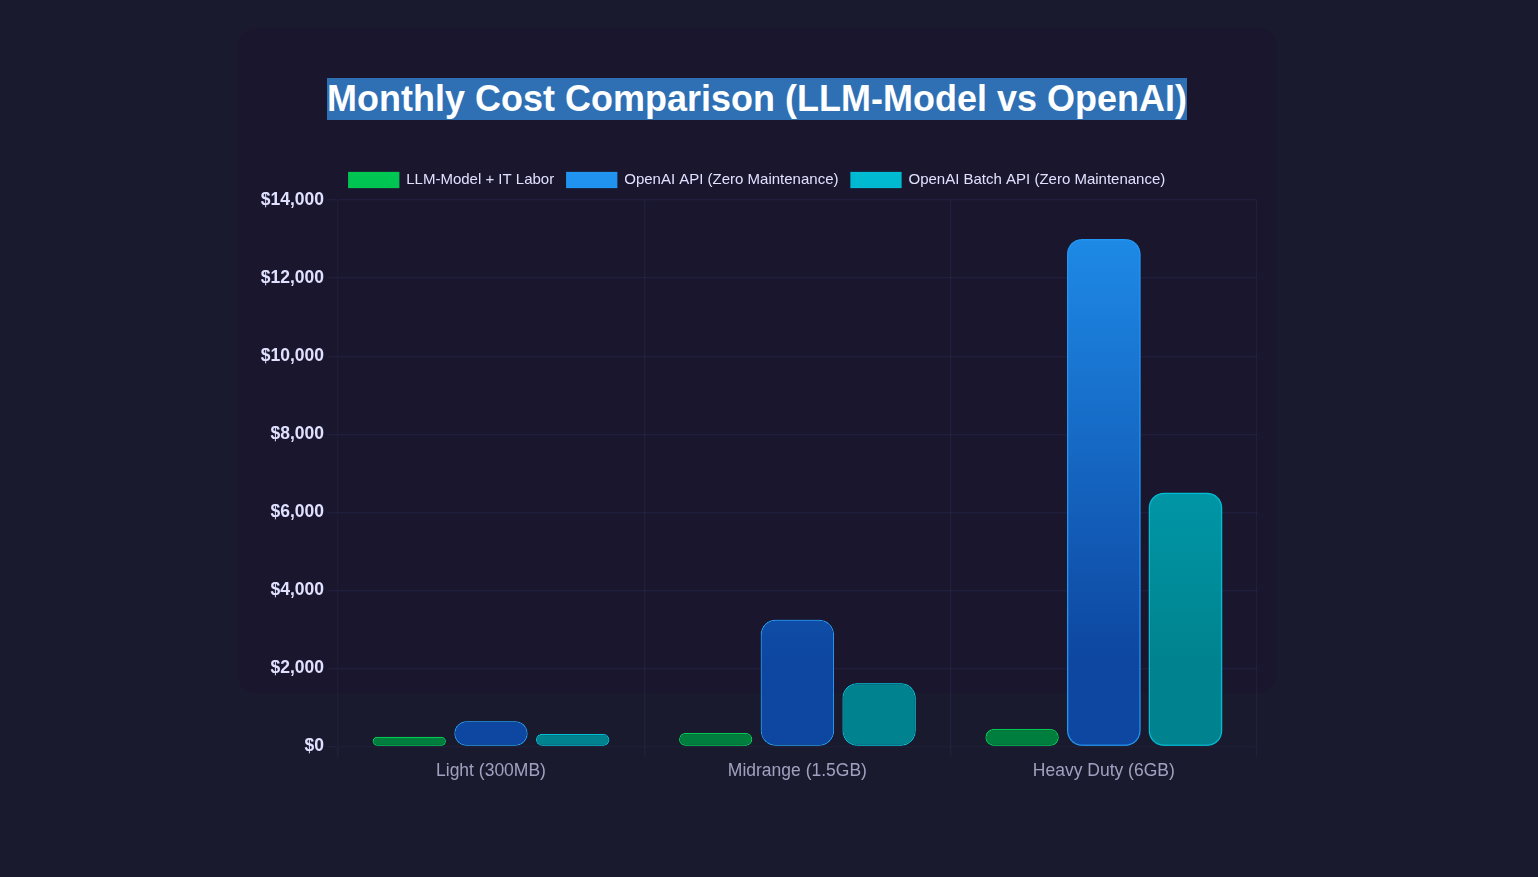
📊 Monthly Cost Comparison Matrix
To match a local LLM-model 70B, we compare it against OpenAI's flagship intelligence tier (GPT-4o / GPT-5.6 Sol) via the unrestricted, pay-as-you-go API.
Note: OpenAI standard API calculations are anchored to active rates ($4.00/1M input, $20.00/1M output per token).
📦 Data Volume Tiers
📦 Light (300 MB / Month)
~100 Million tokens. Ideal for moderate office tasks, daily email flows, or light customer support loops.
🏢 Midrange (1.5 GB / Month)
~500 Million tokens. Ideal for active 8-hour or light overnight scripting, batch scanning customer files, or log parsing.
🏭 Heavy Duty (6 GB / Month)
~2 Billion tokens. Running continuous 24/7 automated pipelines, heavy legal/medical document scanning, or mass data transformations.
⚠️ Hidden Costs of Local AI
Running a local 70B model requires treating that machine like a critical piece of enterprise infrastructure. When you factor in IT maintenance, software updates, pipeline breaks, and monitoring, your "free" local processing suddenly inherits a labor cost.
📊 IT Operational Overhead
Assuming standard IT internal rates or outsourced managed services at ~$75–$120/hr, requiring roughly 2 to 4 hours of maintenance/monitoring per month:
- ✅ Hardware maintenance & updates
- ✅ Software patching & compatibility
- ✅ Pipeline monitoring & troubleshooting
- ✅ Staff training & documentation
🖼️ Architecture Overview

🚀 Getting Started with Unicato24
Hardware Assessment
Expert evaluation of your requirements and procurement guidance
Secure Installation
GPU installation, driver setup, and model configuration
Ongoing Support
Monitoring, patching, updates, and staff training included